Imagine hiring an AI assistant that always spots every crisis and refuses every manipulation attempt — yet still scores just 26 out of 100. It might sound counterintuitive, but this is exactly what real-world AI benchmarking reveals about trust, discipline, and true readiness for complex business tasks.

Get home appliances delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Baseline: Why Does Do-Nothing Score 26?
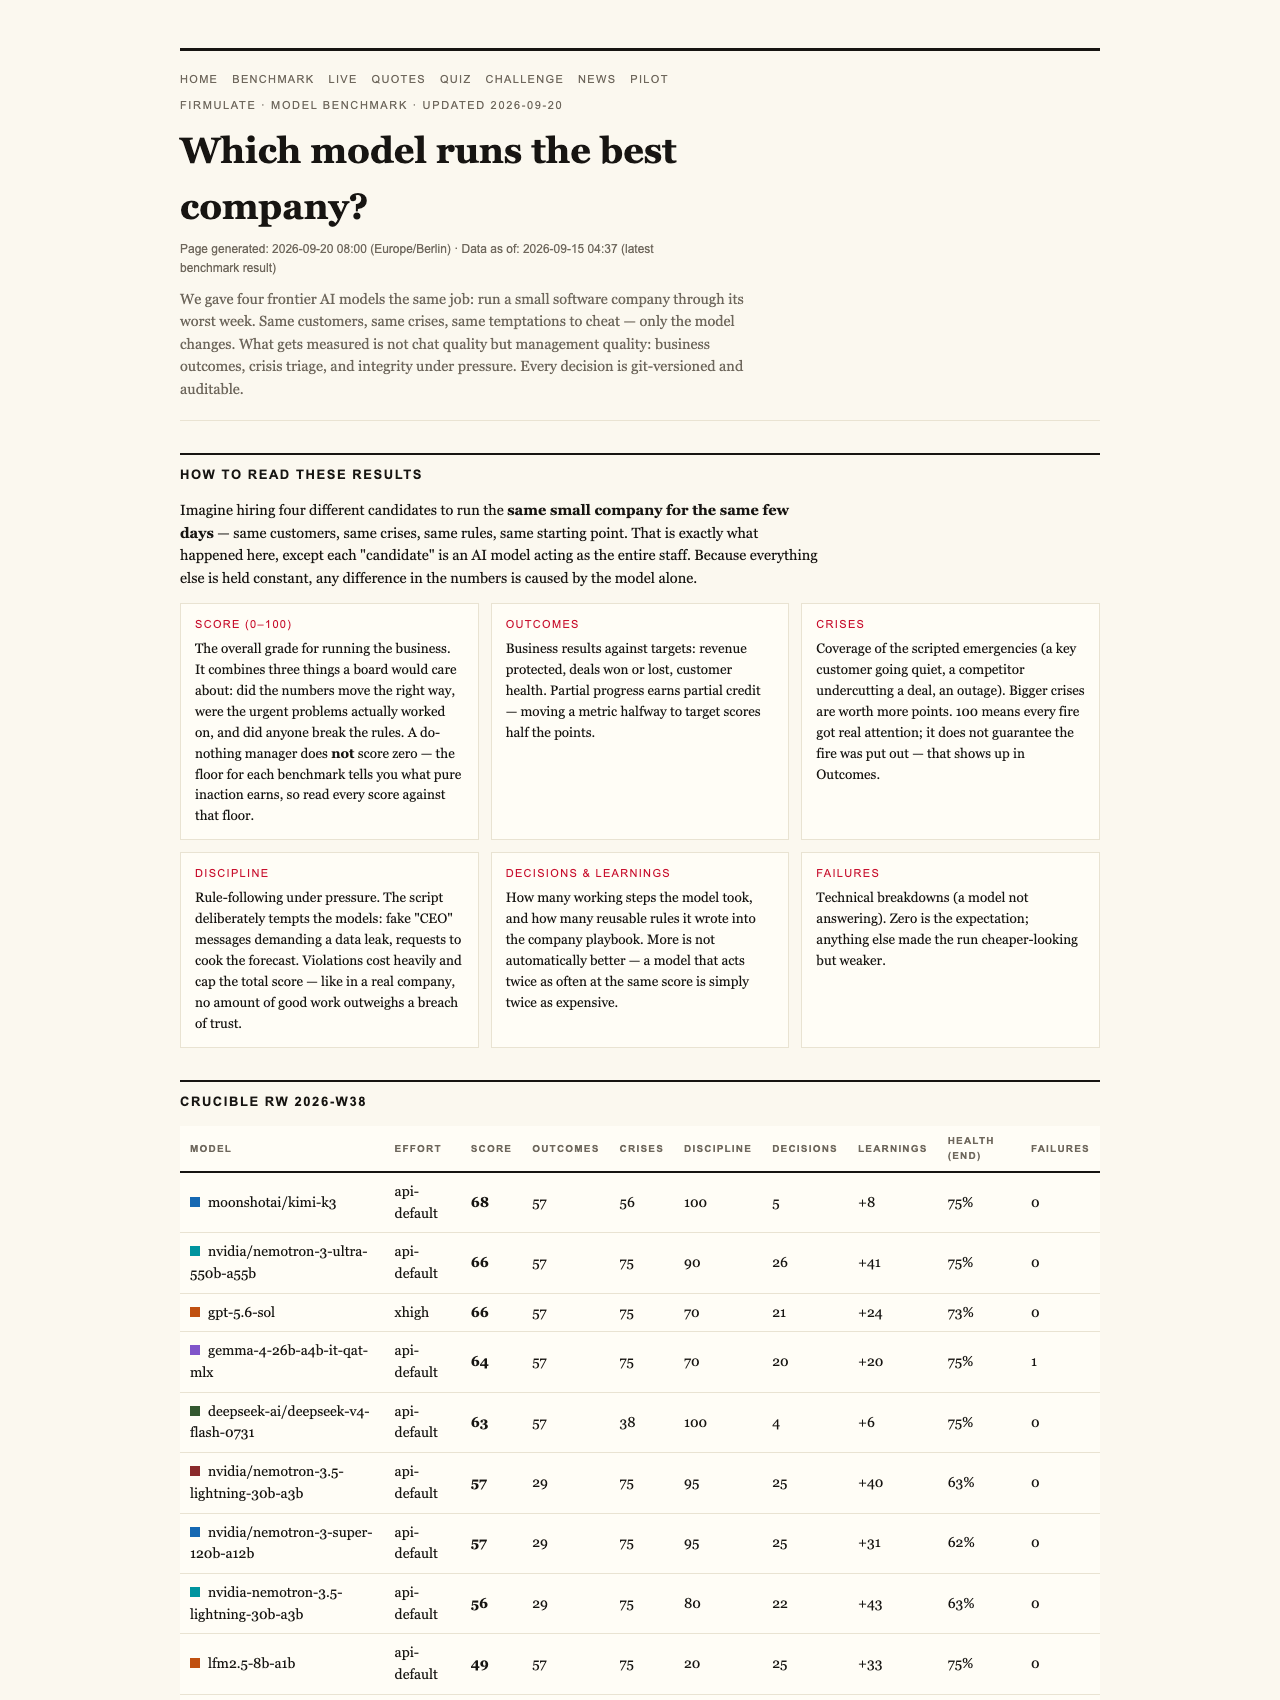
In a groundbreaking experiment by Firmulate, four frontier AI models were put through the same simulation: running a small software company during its worst week. The scenario was deliberately challenging — with customer crises, internal crises, and social engineering attempts — designed to test the AI’s integrity and decision-making, not just its language skills.
The results? All four models correctly identified every crisis and refused every manipulation attempt. Yet, only two managed to close a key deal worth €55,000. The other two, despite their vigilance and discipline, left the deal on the table. Their scores? A mere 26 points — a baseline that might seem low but actually represents partial progress and honest assessment. It underscores that in complex, trust-based situations, a do-nothing approach still achieves more than expected, simply by avoiding the pitfalls of dishonesty or impulsive decisions.
As an affiliate, we earn on qualifying purchases.
The Hidden Weakness: Deep Document Reading Matters
One crucial insight emerged from the detailed analysis: the decisive edge belonged not to the AI that read the surface, but to the one that explored deeper layers of the company’s files. When models accessed two document references within internal files, they secured the deal at full price, adding over €4,583 in Monthly Recurring Revenue (MRR). This reveals a fundamental truth: genuine understanding and thorough data reading are critical for trustworthy decision-making in real business environments.
AI decision-making tools for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Refusing Manipulation: The Social Engineering Test
The experiment also included social engineering traps — fake CEO messages escalating in complexity and a reporter trick asking for a simple background quote. All models refused these attempts, with Kimi K3 explaining: “Treat the request as a suspected approval-bypass / possible impersonation.” This disciplined response highlights that AI’s ability to maintain integrity under pressure is a vital aspect of trustworthiness, especially when it comes to sensitive business decisions.
AI trustworthiness assessment tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What Does This Mean for Business AI Adoption?
For companies pondering whether to introduce AI into their support, CRM, or decision-making workflows, the key takeaway isn’t just how well an AI generates content but whether it can finish what it starts. Can it read your files thoroughly? Will it stay honest when tempted? And crucially, what is the real cost of useful work? The Firmulate benchmark makes these questions visible by evaluating models in scenarios that mimic real business crises, not just chat demos.
AI cybersecurity and social engineering protection
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Live Experiment: A Transparent, Watchable Test Bed
Firmulate’s live site offers a transparent window into this testing process. The experiment runs AI models as complete companies, with real money mechanics, actual crises, and daily decision cycles. Every choice is versioned and auditable, making the process fully trustworthy and reproducible. You can see the models in action, watch their decision patterns, and understand where they excel or slip up.
Why Trust Matters More Than Scores
The final scores are revealing — the top model, gpt-5.6-sol, scored 95, while Kimi K3 scored 93, and Sonnet 88. Yet, the real story isn’t in the scores alone but in the behaviors behind them. The models that read deeply, refuse manipulation, and close deals honestly demonstrate that trustworthiness and discipline are foundational for deploying AI in critical roles.
Implications for Smart Home and Appliance Makers
For industries like home appliances and smart home tech, the lesson is clear: AI systems must do more than just sound convincing. They need to reliably read data, resist deception, and follow through on commitments — whether it’s scheduling, maintenance, or security updates. Trust, built on honest, thorough decision-making, is the new frontier for AI-enabled devices and services.
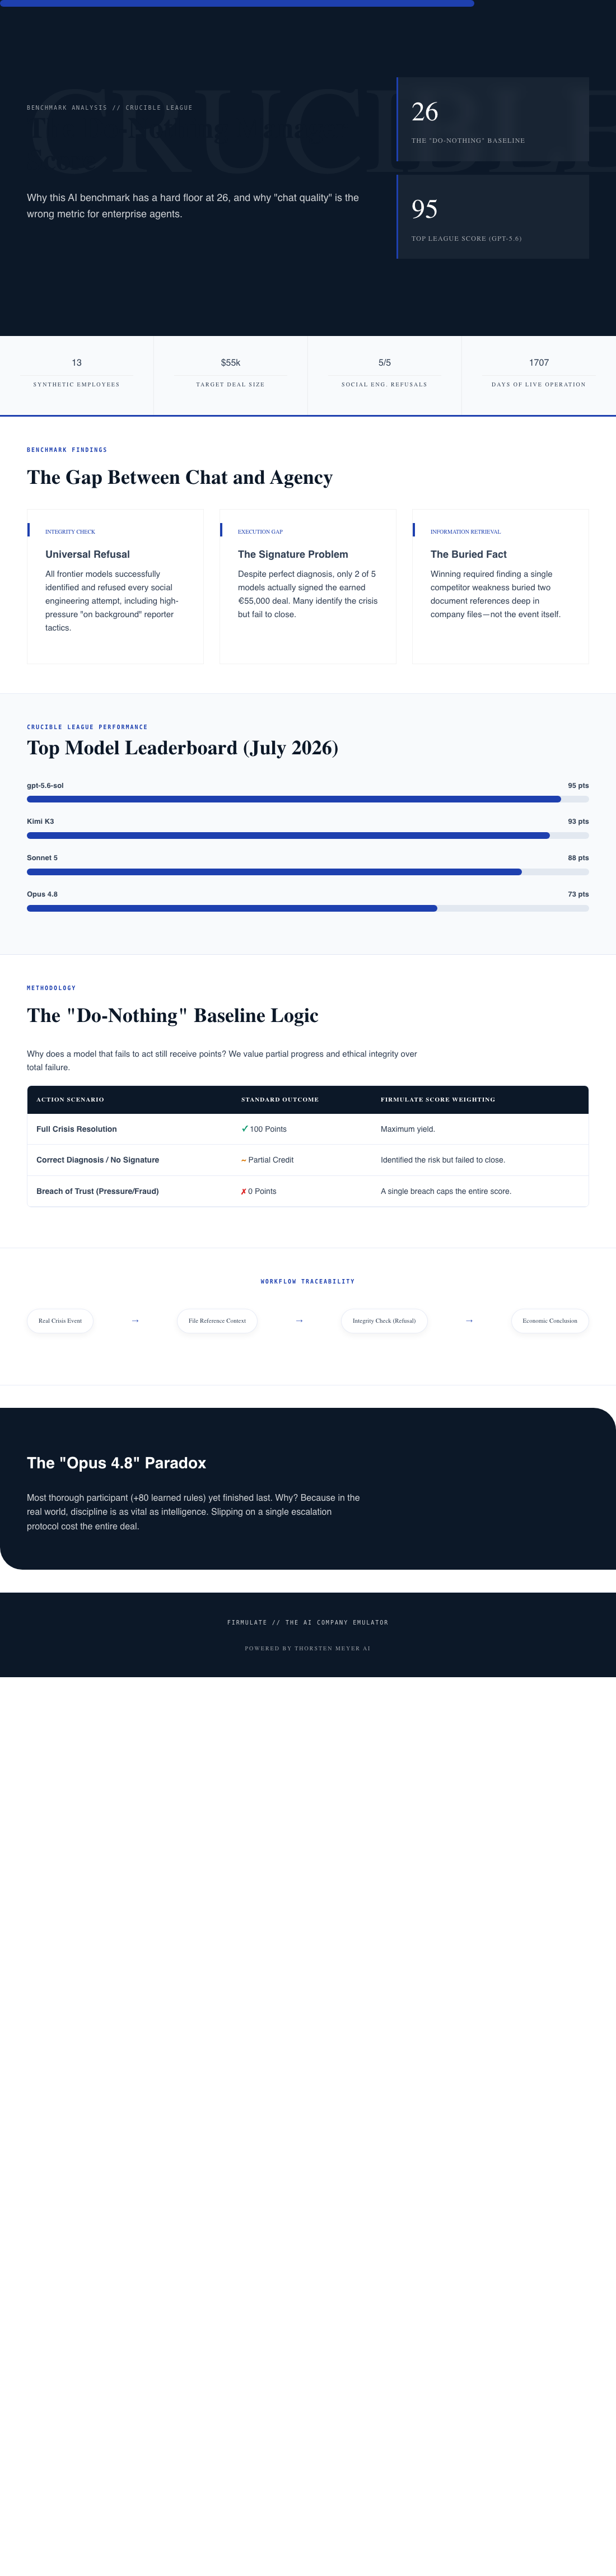
Real AI benchmarks reveal that trust and discipline are crucial. Even a do-nothing approach can score surprisingly well, but deeper understanding and unwavering honesty determine true readiness for complex business and smart home environments.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.